Loom Cairo
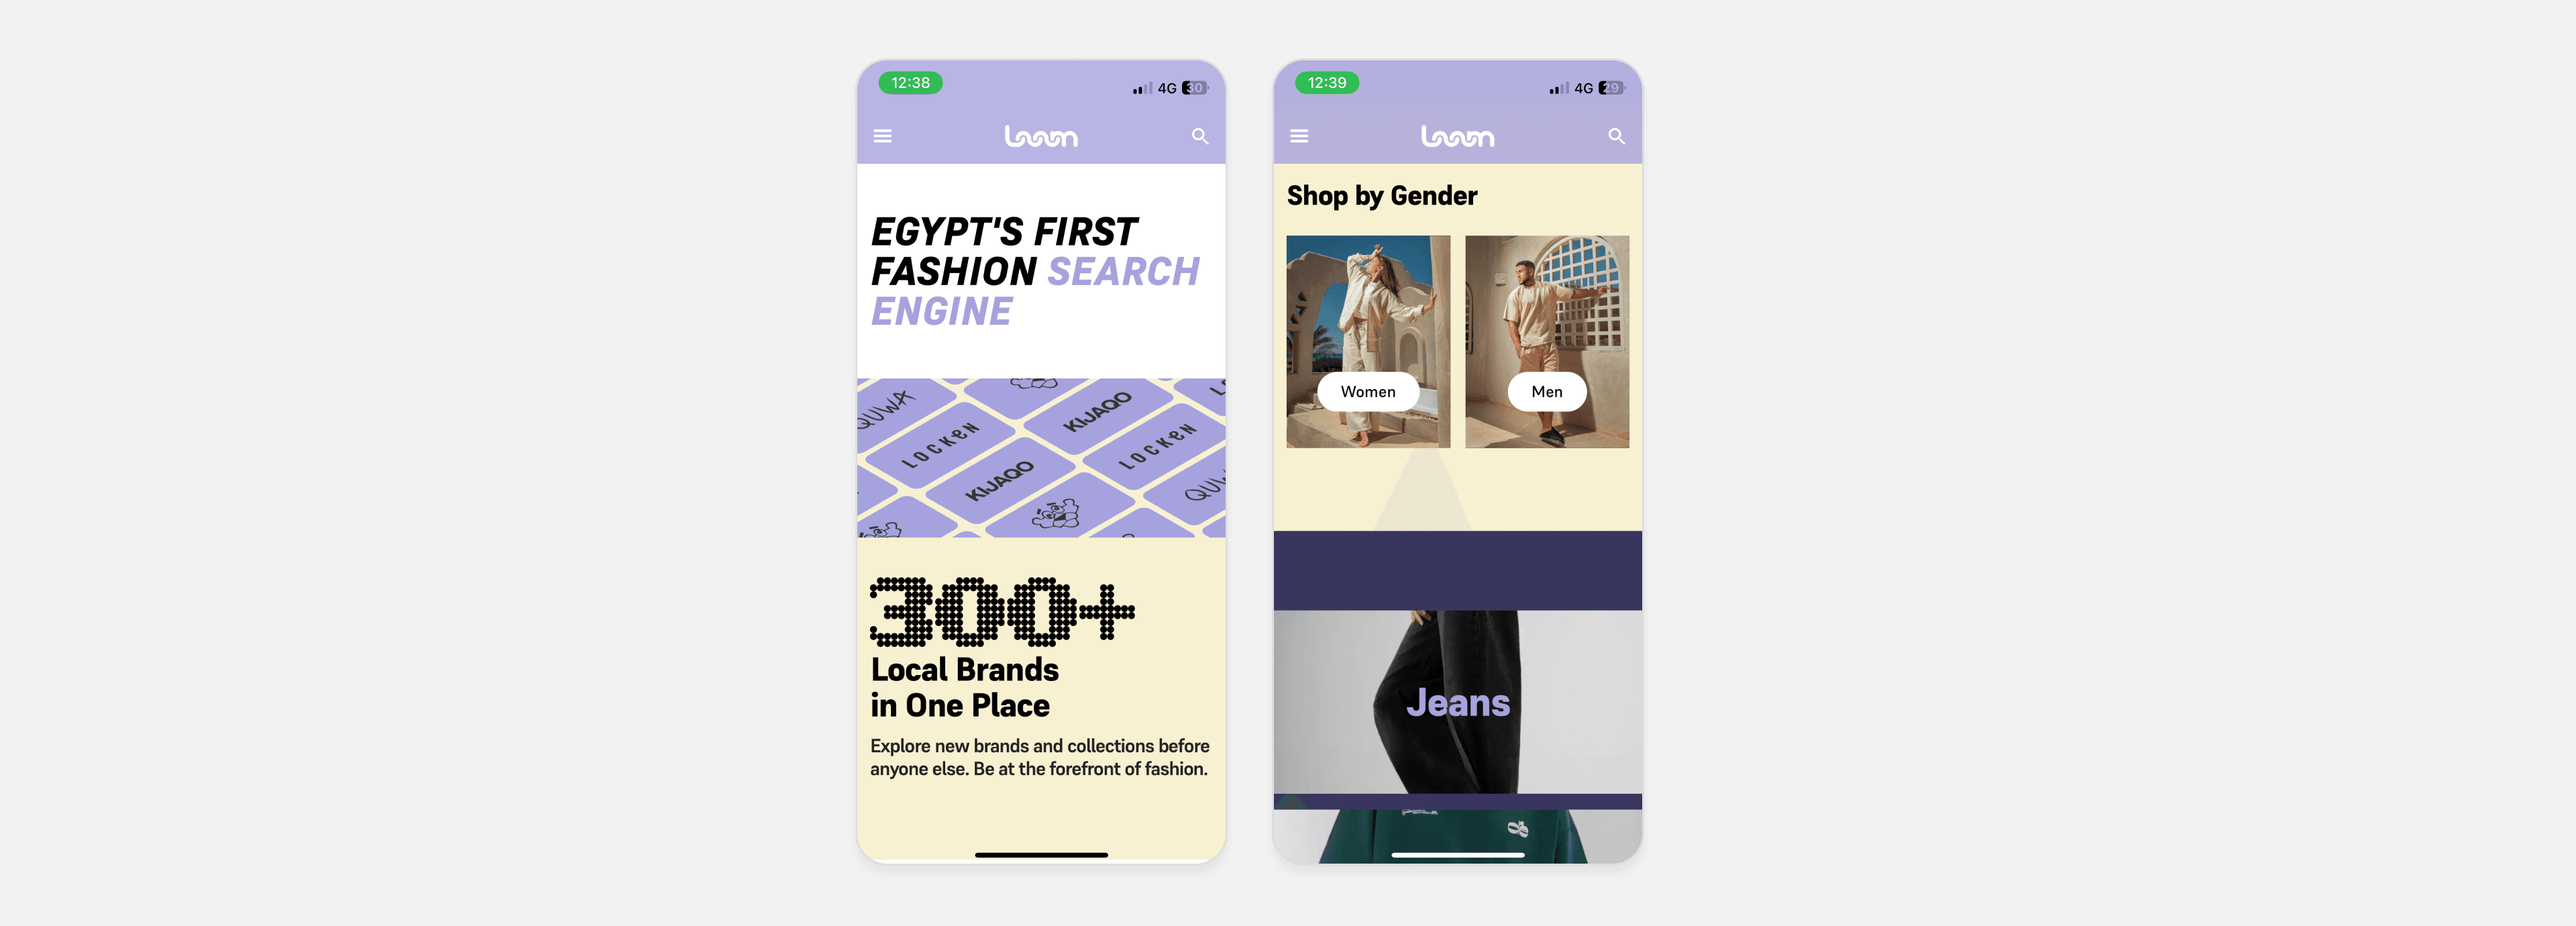
Loom Cairo, later rebranded as Univyr, was a search engine for local fashion that aggregated over 300 Egyptian brand websites into a single platform. Operated 2023 to 2025, reached 70+ brand partnerships and 40,000+ unique visitors at its peak, and was accepted into AUC Venture Lab. It shut down because it never had a place to charge anybody, which is the part of it worth reading.
- Unique visitors, post-TechTalk peak
- 40,000+
- Brand sites aggregated
- 300+
- Brand partnerships
- 70+
- Role
- Founder: solo design and engineering
- Period
- 2023 – 2025
- Stack
- Python, Scrapy, Postgres, Prisma, ZenStack, Redis, Better Auth, AWS S3, TypeScript, Next.js, React, Tailwind, Radix UI, Motion, TanStack Query, Figma
Context#
The Egyptian local fashion scene exploded over the last several years, but buying anything still meant clicking through dozens of brand sites. There was no unified place to discover and filter local fashion. I founded Loom Cairo to solve that, then rebranded as Univyr.
Operated 2023 to 2025. Grew to 70+ brand partnerships and, at its peak, 40,000+ unique visitors. Accepted into AUC Venture Lab (V-Lab). I architected and shipped the full system solo.
The Problem#
The Egyptian Local fashion scene has seen a meteoric rise in recent years. However, users face the cumbersome process of browsing multiple brand websites just to find a single item like a shirt or crewneck. There is currently no unified platform that offers a seamless shopping experience for discovering new fashion pieces, leaving a significant gap in this expanding market.
Web Scraping#
There is a huge variety of brand websites out there: shopify, sllr, elementor, zammit... etc.
I created a web scraper that works with all those different types of websites regardless of their differences. I used bs4 and selenium to do this. This scraper needs to handle a variety of scenarios such as websites that are entirely javascript rendered and others that are server-rendered and return HTML with a simple get request.
To manage this complexity, I fell back to the principles of OOP. I broke down the problem to its simplest parts. I created a class that’s only responsible for an item’s data given its link and a brand’s dictionary (object). This class had to do exception handling to handle the various things that could go wrong and log them. The second part of the problem is discovering the items that exist for each website and interacting with the database.
This taught me a lot about exception handling, abstract methods, class methods, custom exceptions, context manager.
I also read Clean Code during this period which was immensely helpful. I picked a few things such as function cohesion, coupling, abstraction levels, private methods, and the value of unit tests... etc.
Labelling Algorithm & Data Analysis#
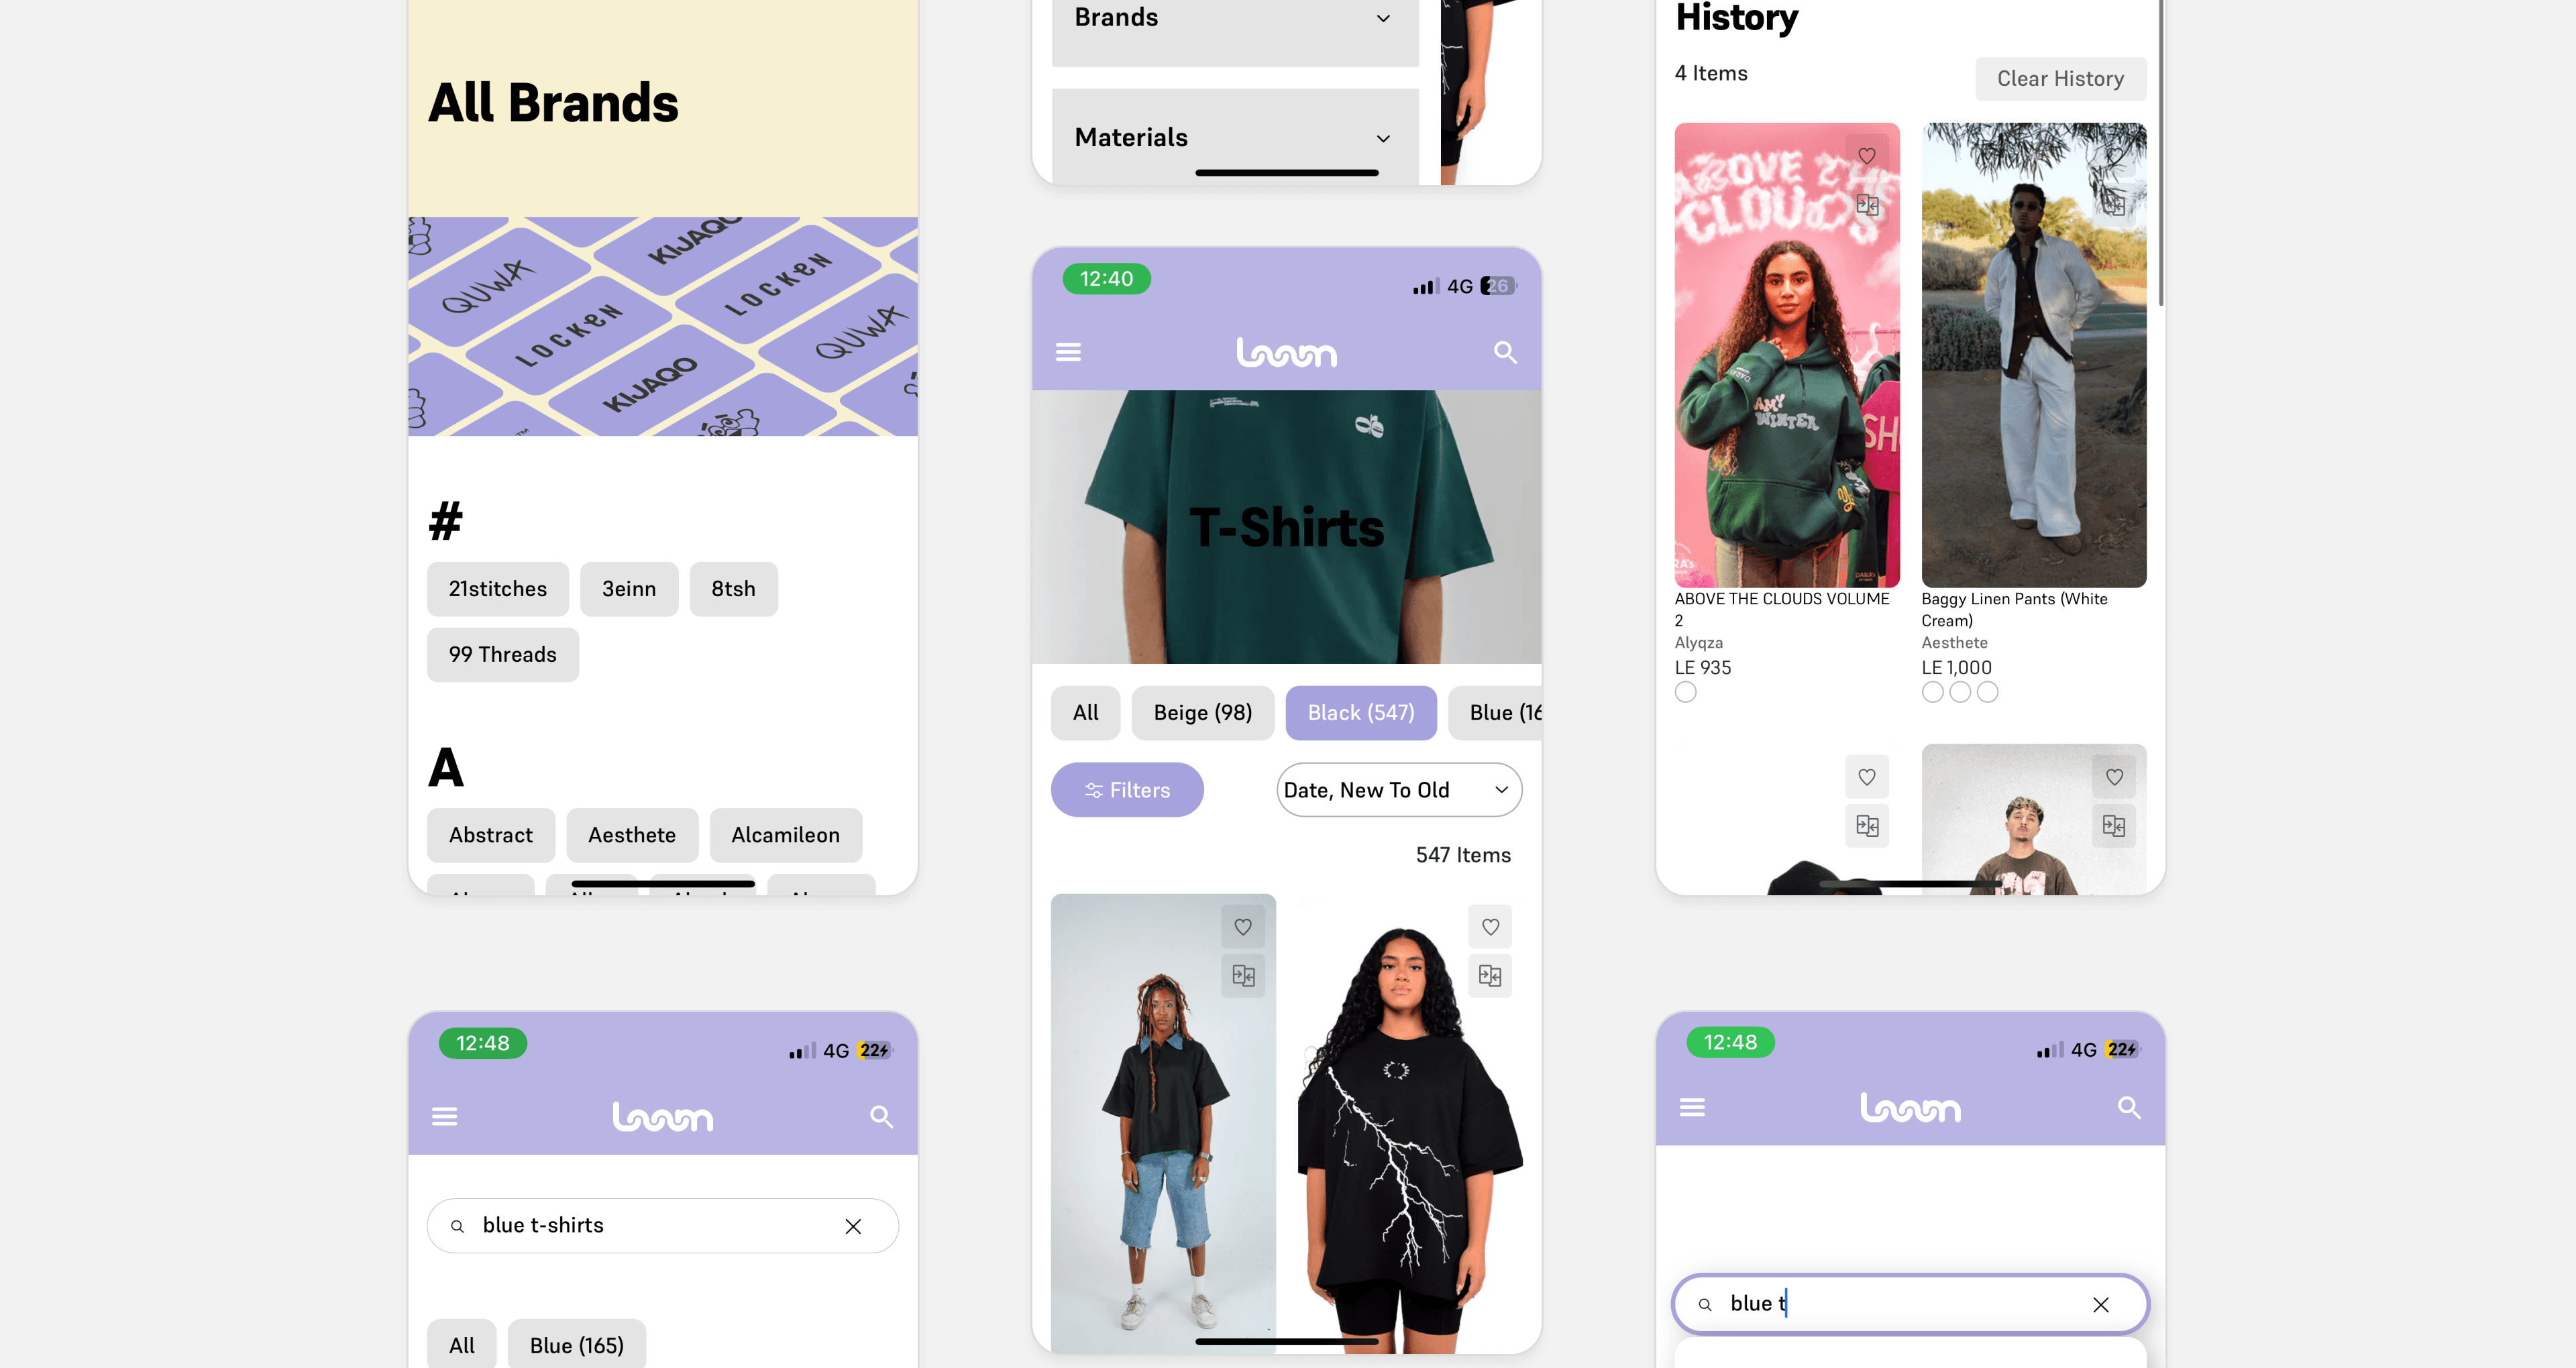
To enable the filters and improved search, I created an algorithm that labels the items. The loom database is quite large: 20,000 items, 92,000 images, and 8,059 distinct raw size strings, because every brand writes its sizes its own way. That is the catalogue Loom kept live across its partner brands, not what a crawl moves; after the Univyr rebuild below, a single run reads far more than it retains. I started out with cleaning and preprocessing the data such as fixing spelling inconsistencies, such as blue and bluee. Then, I did data normalization by grouping together synonyms of colors such sky and blue into a single parent color. All of it collapses down to 19 canonical colours, 19 materials and 48 categories, which is what makes a filter panel possible at all.
Based on the uncovered synonyms, inconsistencies, and data gathered from the original websites, I created a labeler that works really well on new items from new brands. It enables very rich filters and search all automatically.
Try to go on other platforms and search for White Shirt and see which one has the most relevant results!!
Database Schema Design and Optimization#
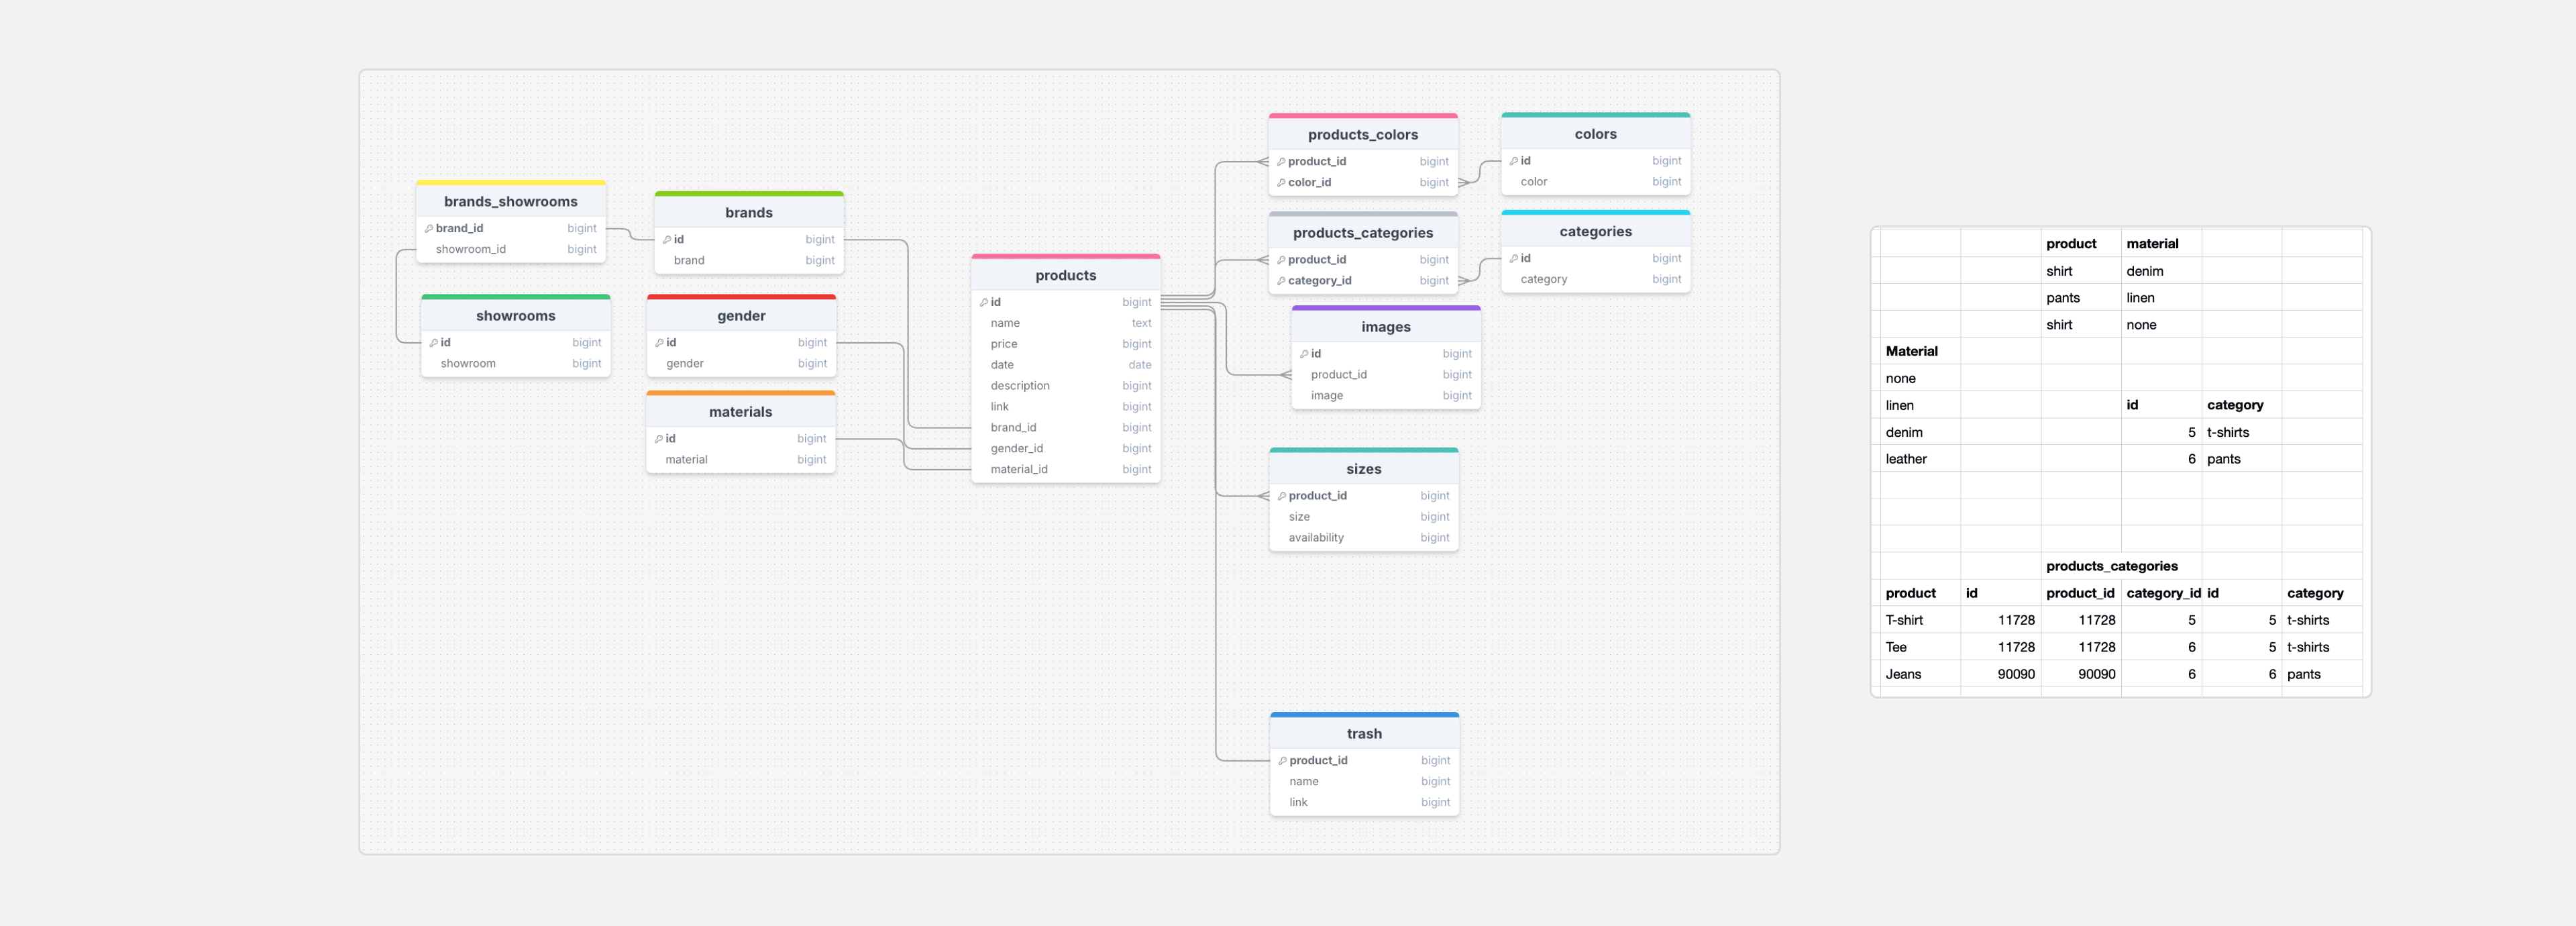
I used SQLite to create my database. It started with the database schema. I created a database that was performant and scalable. To achieve this, I ensured that my database was normalized by using lookup tables for values that are repeated such as brands (this way i could have a single source of truth) and relating the various things using many-to-many relationships.
I also used constraints to ensure data integrity at the database level. I also implemented triggers to ensure data is synced across related tables. Indices were used to speed up the performance of certain queries by orders of magnitude. A de-normalized view was created to simplify interaction with the database in the API.
API#
I created the API with flask. There are various endpoints. The search endpoint parses out words to detect if filters exist for those words otherwise it does a Full-Text Search. Other endpoints fetch metadata that’s needed for filters. The SQL queries are quite optimized as I have deep knowledge of the database schema, using the proper indices (based on B Trees).
The explain query plan and timer come in really handy for optimization in those scenarios. I was able to get most queries down to sub 50ms response, especially the ones that do a lot of heavy lifting.
UX/UI Design with Figma#
Because the majority of users will be on mobile, and it’s easier to add complexity rather than it is to simplify a complex thing. A mobile-first approach was the apparent way to go for design.
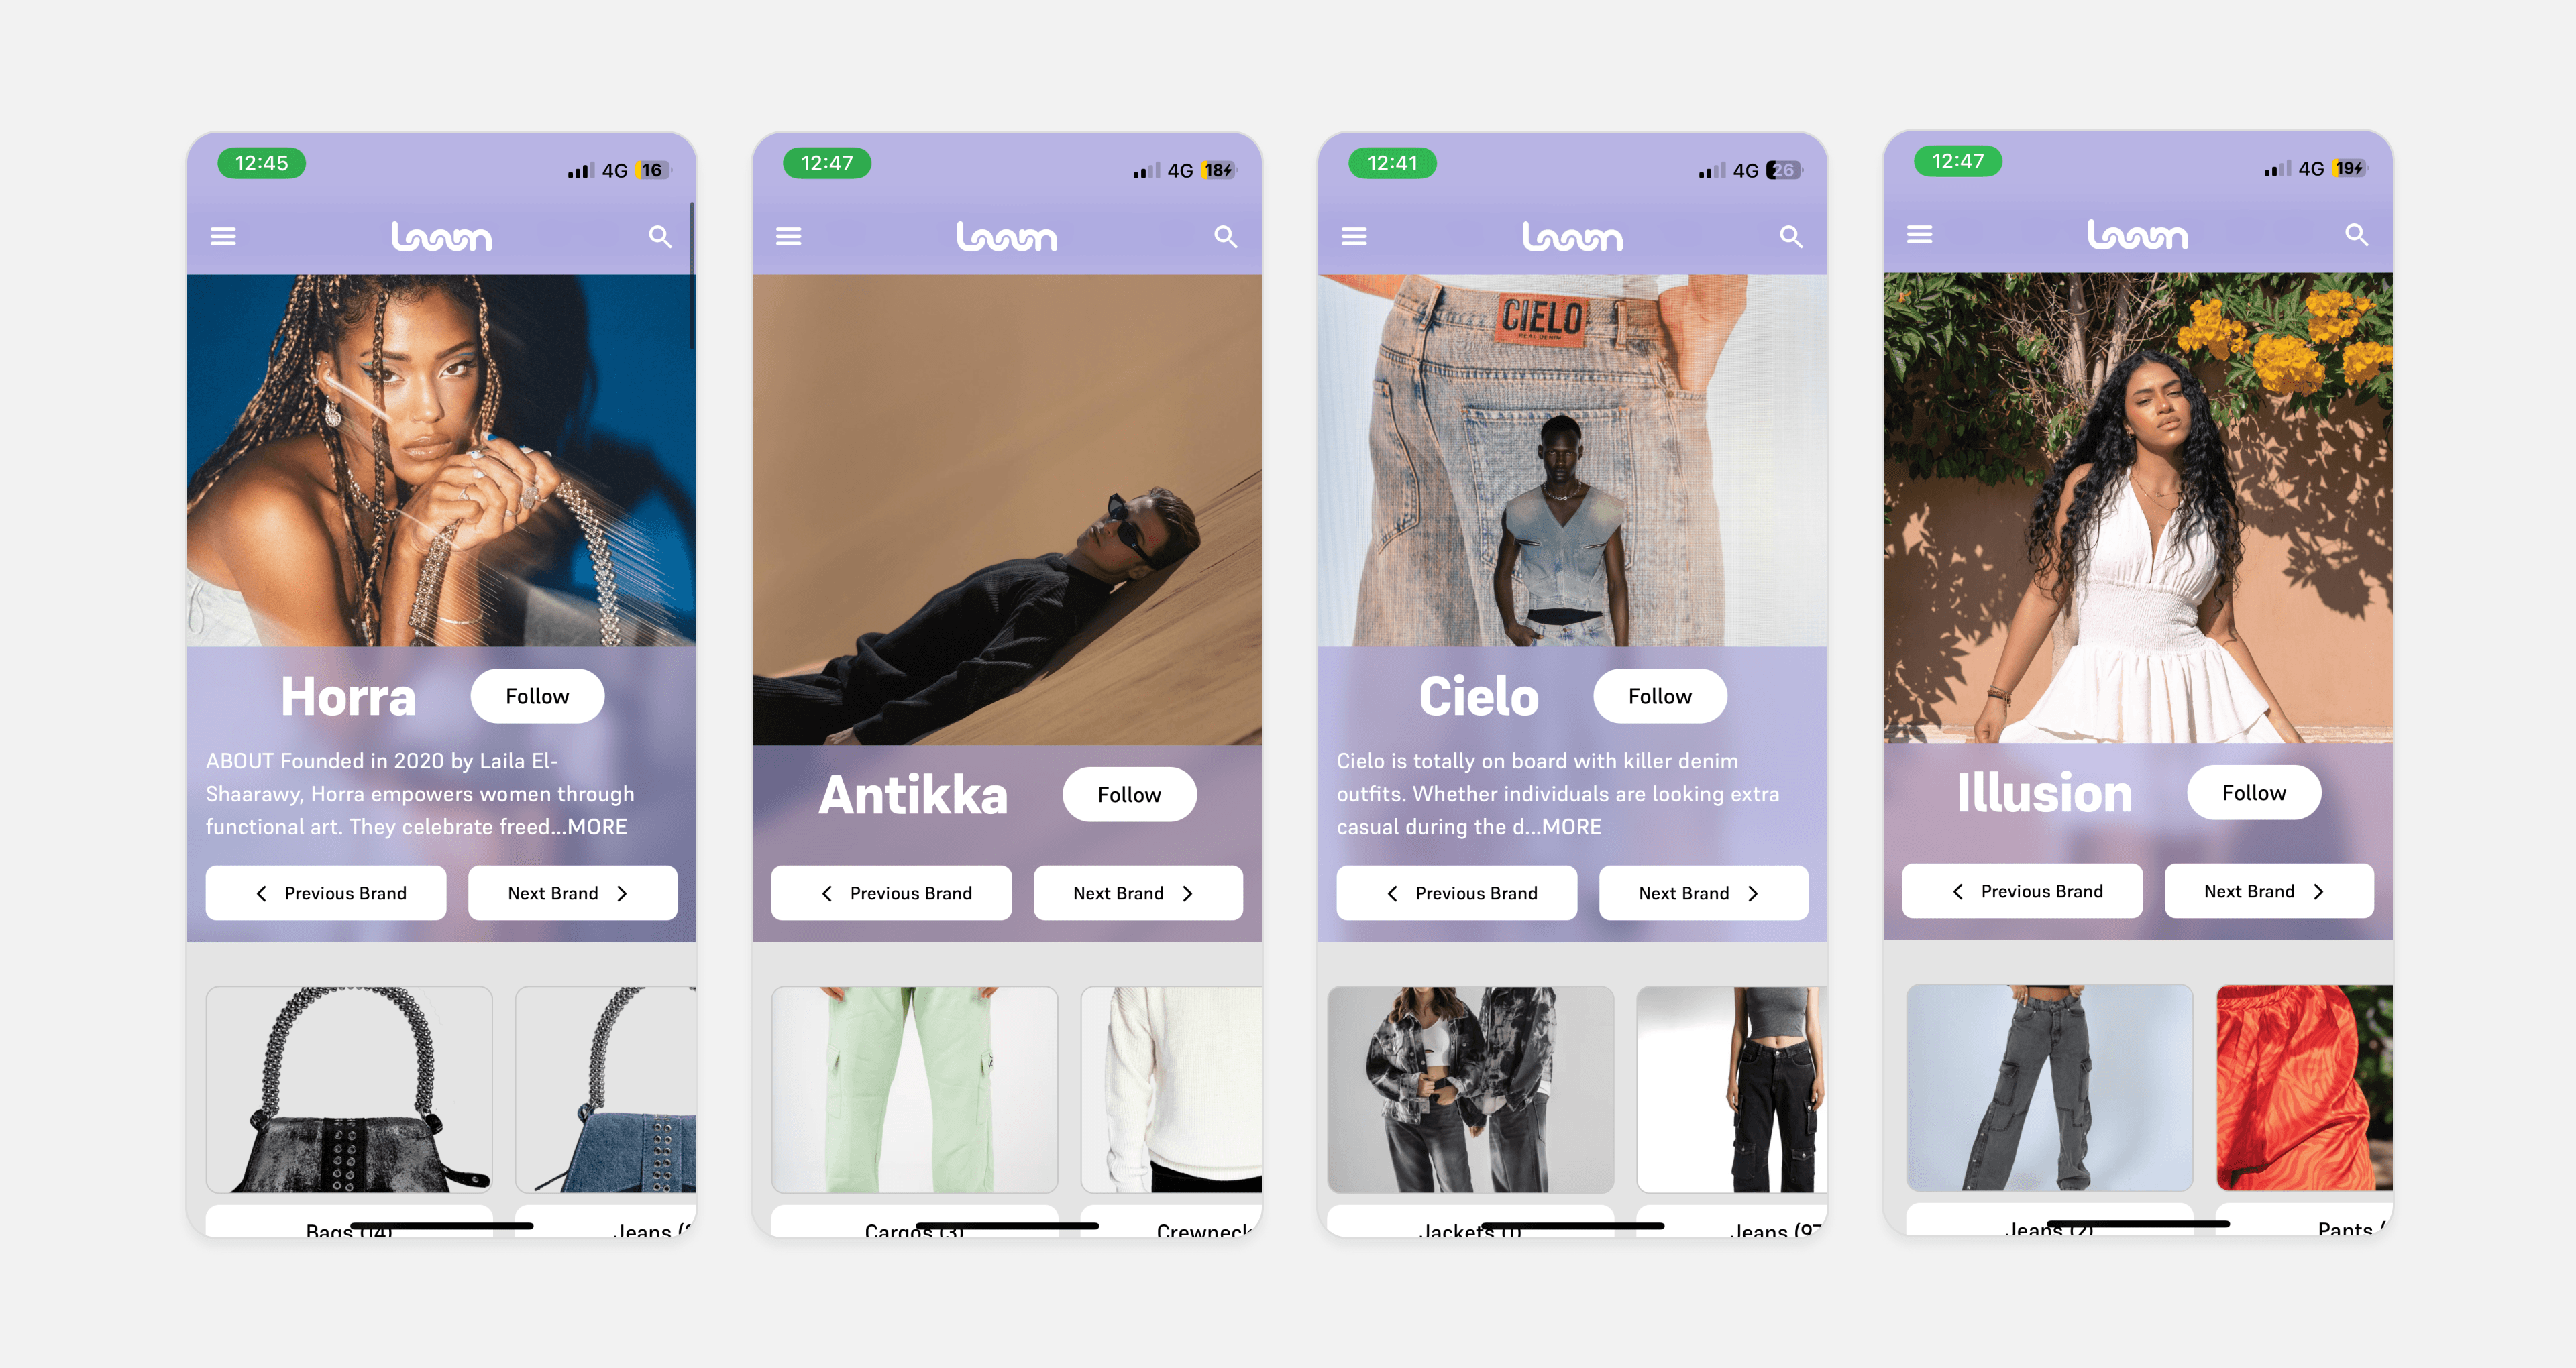
I researched the patterns that users are used to. I picked the brand colors, typography, a typescale and created the main layouts. I also created a design system to ensure consistency of design throughout the app using figma components. The designs respected the rules of hierarchy, consistency, white space, contrast, alignment, and balance.
React Web App#
For the web app, I used React, vite, react-router, radix-ui, and vanilla CSS. I made use of CSS resets. global variables to ensure consistency of styles, and a typescale system. The website displays the items in a really unique way and has a bunch of cool stuff. Reusable components and pages of course, and a bunch of steps to ensure optimal performance. There’s search with autofill. History, likes, followed brands and a cart they can all keep track without the user having to login.
This web app received praise from numerous users.
Migration to Univyr#
As scale grew, the early SQLite and Flask stack was rebuilt on Postgres with Prisma, ZenStack and Redis caching. ZenStack owns the schema language, which means row-level access policies are declared next to the models and enforced by one enhanced client rather than re-checked in every handler.
Search was rebuilt rather than replaced. A weighted tsvector ranks the item name above its URL slug above its description, behind a GIN index, with two custom Postgres functions doing the unglamorous work: one masks the tokens the English stemmer would mangle, so tee and polos and half the brand names survive, and one mines the last path segment out of the product URL. In front of that sits an n-gram parser that slides 4-grams down to 1-grams across the query and matches each against five hand-built synonym dictionaries, largest first so the long matches win. It strips what it matched out of the query and only full-text-searches the leftovers, so “blue linen shirt from antikka” arrives at the database as four structured facets and an empty text search.
The scraper was rewritten from BeautifulSoup and Selenium onto Scrapy, and stopped parsing HTML at all: most Egyptian brands run Shopify, so it reads the products JSON endpoint directly and validates every response against a Pydantic model, which turns a brand silently changing its catalog shape into a logged error attributed to that brand. Writes go in as bulk upserts through a four-stage dependency order inside one transaction per brand. Fifty requests run in parallel across brands but only one at a time per domain. A full run reads about 43,000 brand sites and lands roughly a million items and four million variants in about twenty minutes.
Labelling stayed deterministic. The synonym dictionaries do the work, and the vision classifier that would replace them is still a prototype rather than a shipped system.
Auth moved from a signed session cookie to Better Auth, with organisations for multi-tenancy, two-factor, Google One Tap, and Apple, Google and TikTok sign-in. The product was rebranded as Univyr and the surface was redesigned end to end in Figma.
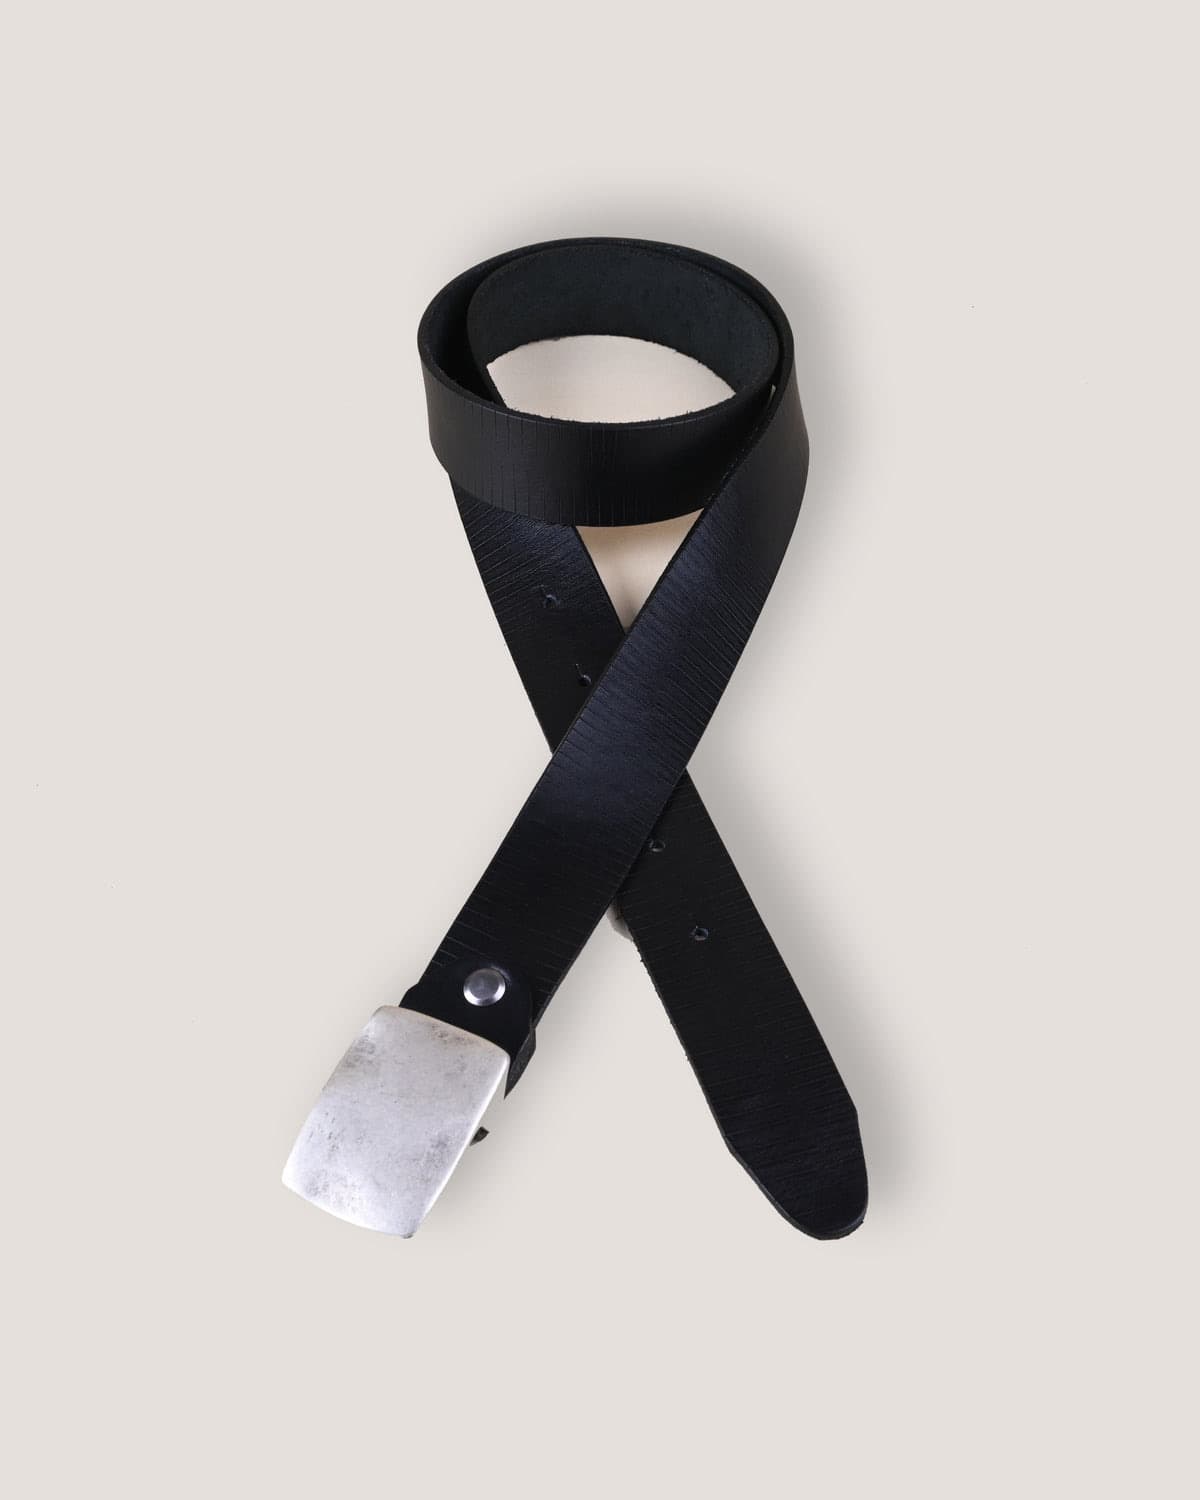
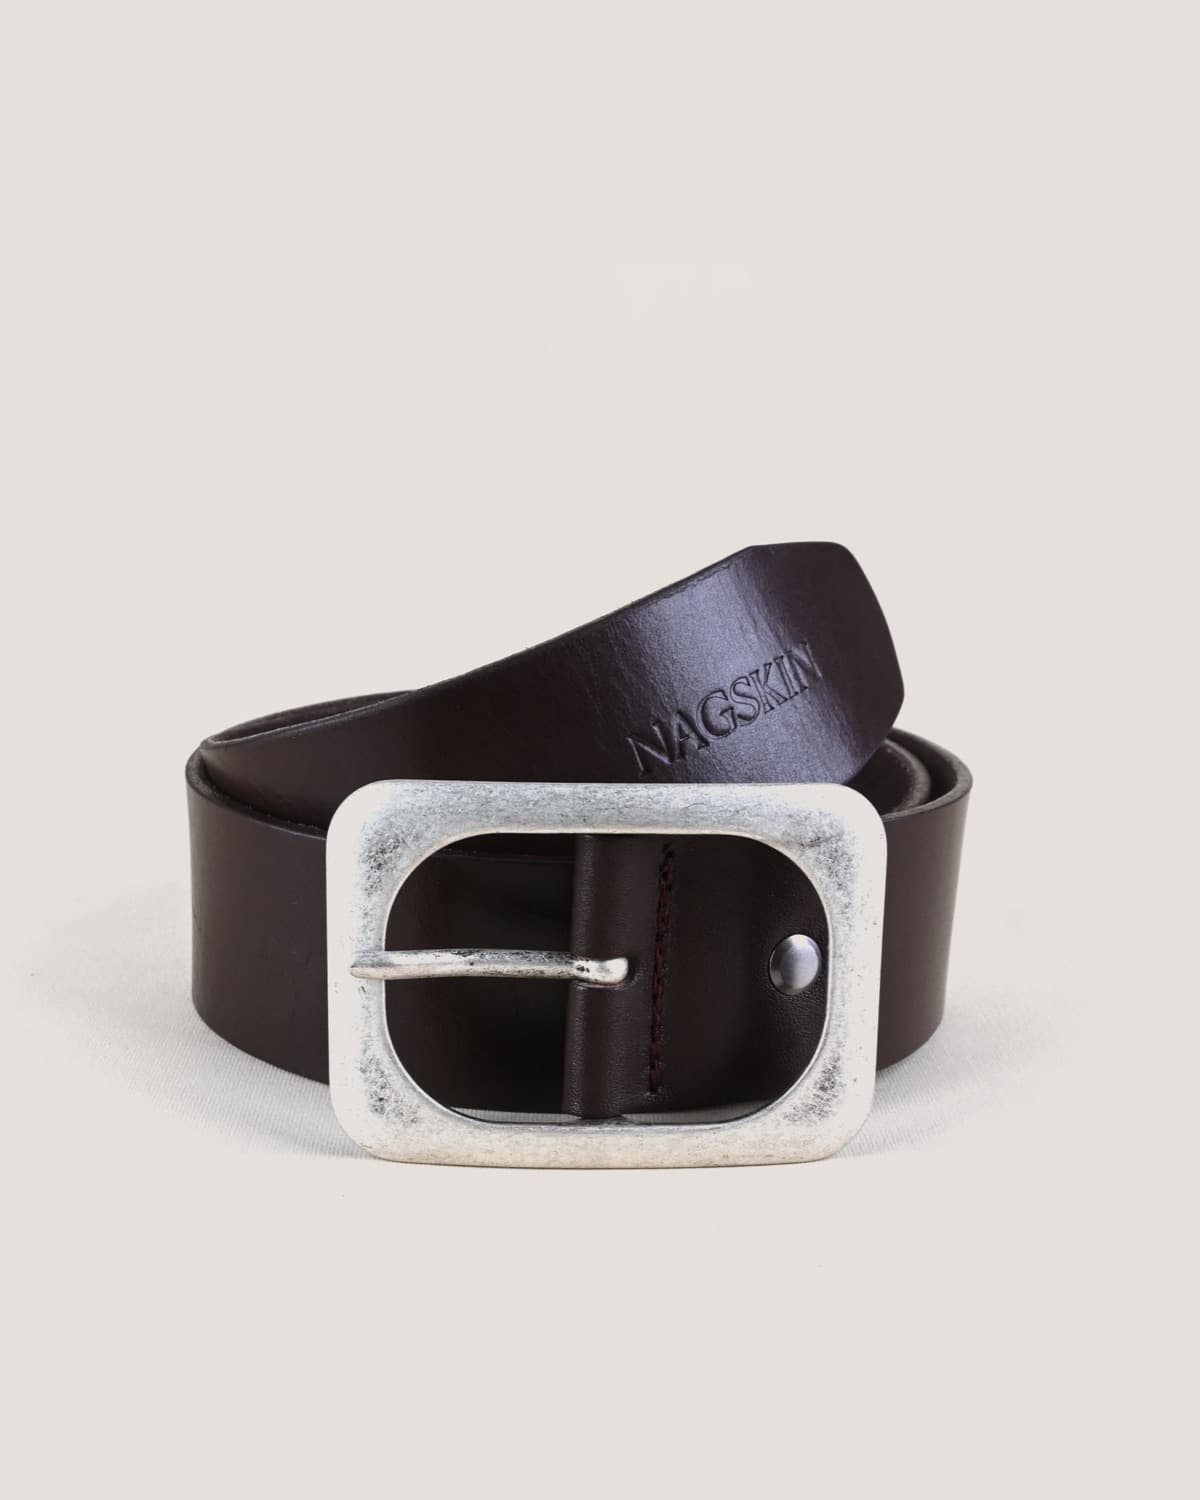
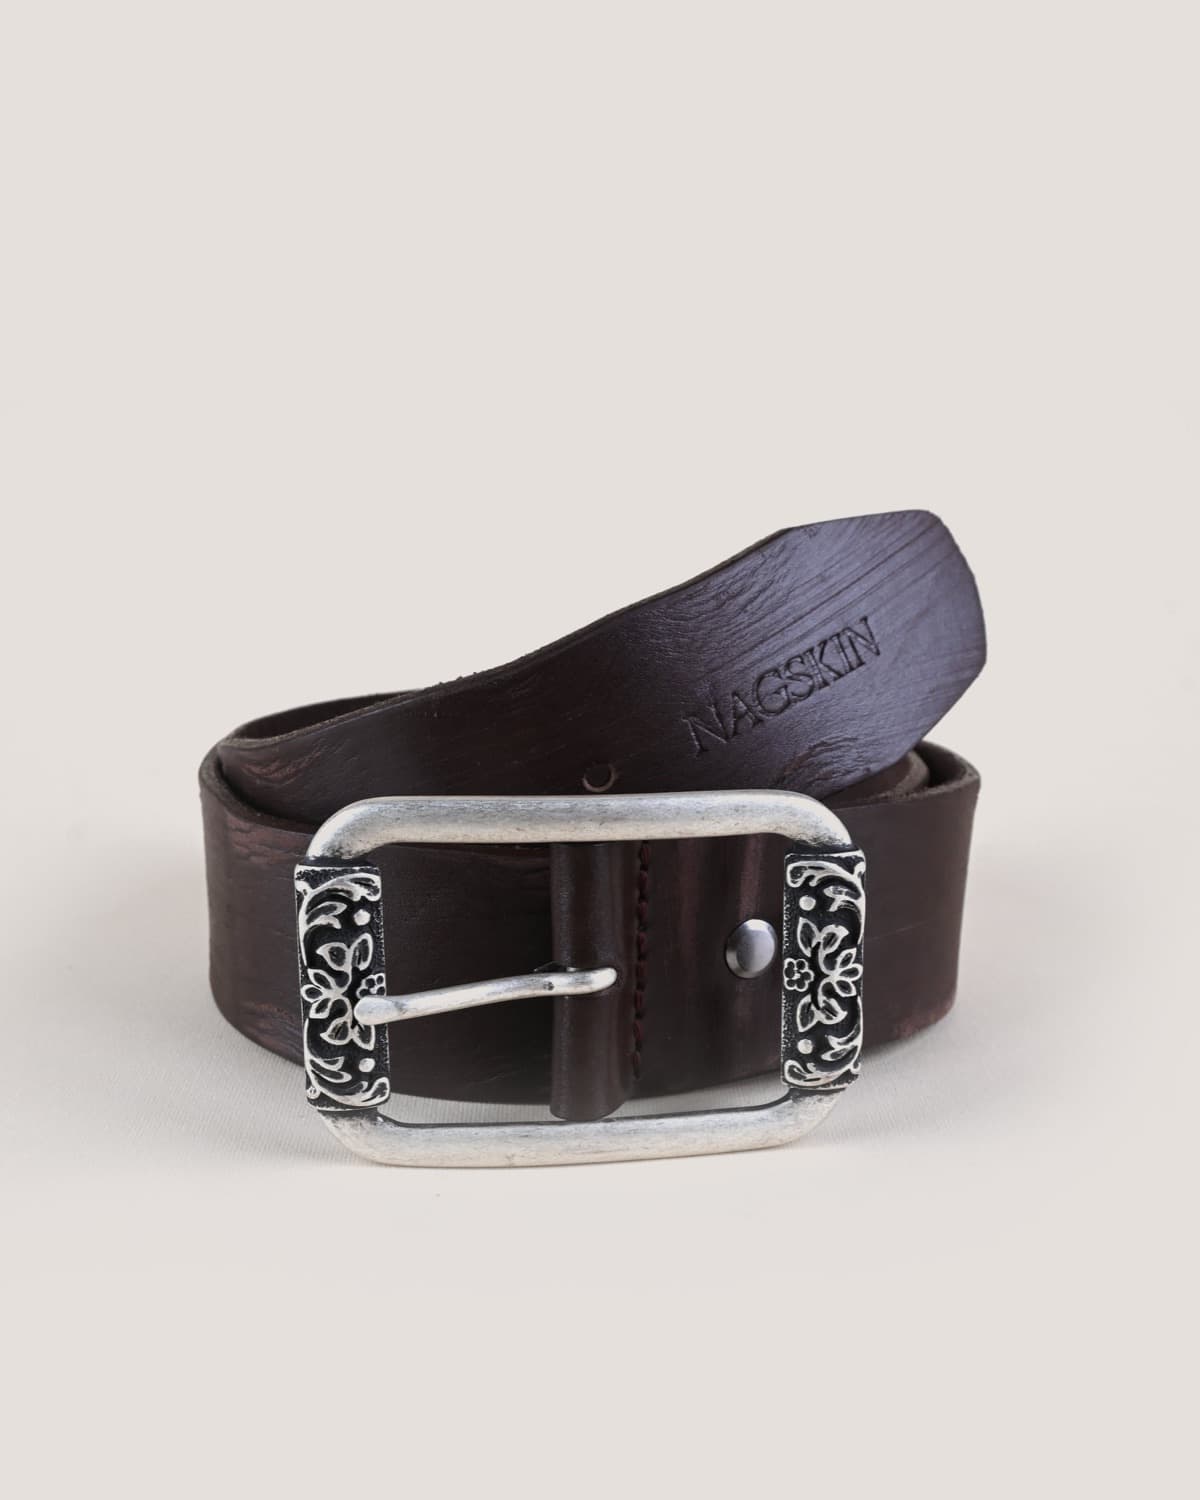
The storefront was rebuilt in Next.js. The block below is its product gallery, running here as it shipped.
savi
LE 1,800.00
Why it ended#
In June 2025 I pitched Univyr at AUC Venture Lab: $150K for 10%. The traction slide was honest and, for its size, good: 4,700 monthly active users, 76% of them returning, 3.5 minutes of average retention against a market average of two. It did not close. The objection was not the growth and not the engineering; it was that nobody could point at the moment money changed hands. An aggregator that sends free traffic to brands it does not take a cut from has 300 suppliers and no customers.
Then the demand showed up anyway. A TechTalk appearance put the product in front of a national audience and traffic went to 40,000+ unique visitors, roughly eight times the base it had been growing off. I do not have retention data from that window (the analytics went with the product), so I will not claim the spike stuck. What I can say is the thing that matters: the biggest audience Univyr ever had arrived after the raise had already failed, and there was still no toll booth for them to walk through. The investors had been right, and the traffic proved it rather than rescuing it.
The mistake was not the scraper or the search or the two years. It was sequencing: I built a supply-side pipeline of real technical difficulty for a market where I had never established who pays, and by the time the answer mattered the only lever left was a raise. The rule I took out of it is unglamorous and I have applied it since: find the point where money changes hands before building the thing that depends on it. Wholana has seat billing in it, and paying users on it, because this one did not.